|
Jiashuo Yu I'm currently working as a researcher at Tencent. My research mainly focuses on audio-visual learning, video understanding, and MLLM. I am among the core contributors of InternVideo, Intern-S, VBench, VideoChat, and the Jen Music model series. I received my M.S. from the School of Computer Science, Fudan University in 2022. Before joining Tencent, I worked at Shanghai AI Laboratory on video understanding and MLLM mid-training, and at JenMusic AI on music generation. Email / Scholar / Github / HuggingFace / X |
|
News
|
Research* denotes equal contribution. |
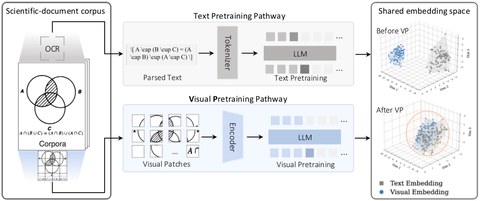 |
Intern-S2-Preview: Scientific Agentic Foundation Model
Intern-S Team arXiv, 2026 arXiv / model Scientific agentic foundation models built with scientific multimodal pre-training and a unified SFT, multi-task RL and agentic RL post-training pipeline; the 397B model extends time-series modelling to numerical forecasting. |
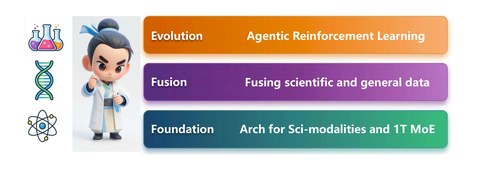 |
Intern-S1-Pro: Scientific Multimodal Foundation Model at Trillion Scale
Intern-S Team arXiv, 2026 arXiv / model The first one-trillion-parameter scientific multimodal foundation model, covering 100+ specialized tasks across chemistry, materials, life sciences and earth sciences, with stable RL training at trillion scale. |
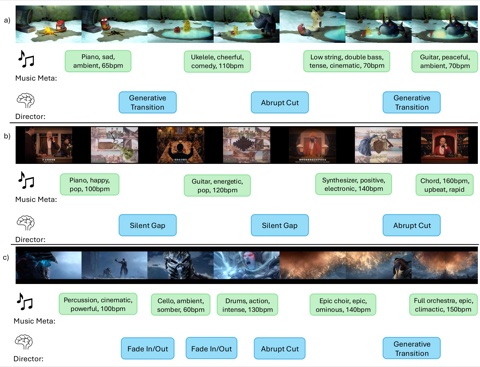 |
JenBridge: Adaptive Long-Form Video Soundtracking across Scene Transitions
Jiashuo Yu, Yao Yao, Boyu Chen, Alex Wang arXiv, 2026 arXiv A flow-matching music generator with dual text-visual conditioning and an LLM "director" that picks transition styles produces coherent soundtracks for long videos with many scene changes. |
 |
Jen 1.5 & Jen 1.6+: Ethically-Trained High-Fidelity Music Generation Models
Jen Team JenMusic AI, 2024–2025 platform / Jen 1.6+ announcement The text-to-music models behind the Jen platform, trained only on fully licensed catalogs. Jen 1.5 (Nov 2024) and Jen 1.6+ (Apr 2025) progressively improve tuning, audio quality and fidelity for high-fidelity music generation from text prompts. |
 |
InternVideo3: Agentify Foundation Models with Multimodal Contextual Reasoning
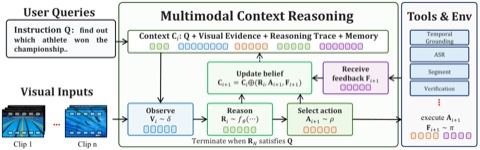
Ziang Yan*, Sheng Xia*, Jiashuo Yu*, Yue Wu*, Tianxiang Jiang, Songze Li, Kanghui Tian, Yicheng Xu, Yinan He, Kai Chen, Limin Wang, Yu Qiao, Yi Wang arXiv, 2026 arXiv / code Treating long-video understanding as closed-loop evidence accumulation over a shared multimodal context, with KV-cache-compressing latent attention, turns a video foundation model into a tool-using video agent. |
 |
VRBench: A Benchmark for Multi-Step Reasoning in Long Narrative Videos
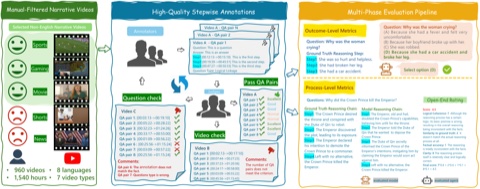
Jiashuo Yu*, Yue Wu*, Meng Chu*, Zhifei Ren*, Zizheng Huang*, Pei Chu*, Ruijie Zhang, Yinan He, Qirui Li, Songze Li, Zhenxiang Li, Zhongying Tu, Conghui He, Yu Qiao, Yali Wang, Yi Wang, Limin Wang ICCV, 2025 arXiv / code 960 long narrative videos (1.6 hours on average) with 8K multi-step QA pairs and 25K timestamped reasoning steps, evaluated at both the outcome and the reasoning-process level. |
 |
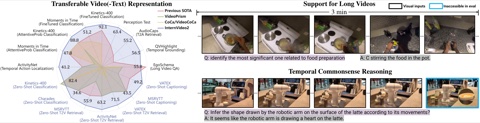
InternVideo2.5: Empowering Video MLLMs with Long and Rich Context Modeling
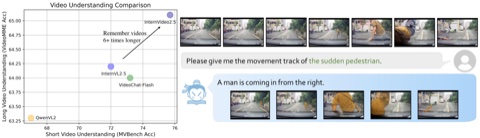
Yi Wang*, Xinhao Li*, Ziang Yan*, Yinan He*, Jiashuo Yu*, Xiangyu Zeng, Chenting Wang, et al. arXiv, 2025 arXiv / code Long and rich context modeling, via preference optimization on dense vision tasks and adaptive hierarchical token compression, improves both fine-grained perception and long-video understanding of video MLLMs. |
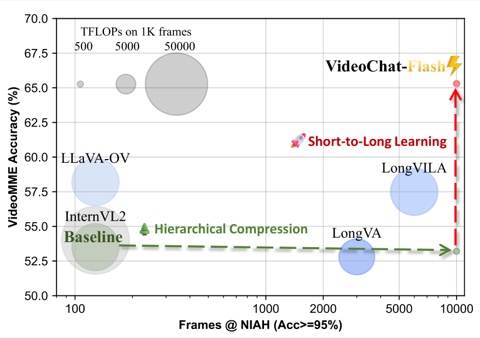 |
VideoChat-Flash: Hierarchical Compression for Long-Context Video Modeling
Xinhao Li*, Yi Wang*, Jiashuo Yu*, Xiangyu Zeng, Yuhan Zhu, Haian Huang, Jianfei Gao, Kunchang Li, Yinan He, Chenting Wang, Yu Qiao, Yali Wang, Limin Wang ICLR, 2026 arXiv / code Hierarchical clip-to-video token compression (~1/50) with almost no performance loss; reaches 99.1% needle-in-a-haystack accuracy over 10,000 frames. |
 |
InternVideo2: Scaling Foundation Models for Multimodal Video Understanding
Yi Wang*, Kunchang Li*, Xinhao Li*, Jiashuo Yu*, Yinan He*, Guo Chen, Baoqi Pei, Rongkun Zheng, Jilan Xu, Zun Wang, et al. ECCV, 2024 arXiv / code A 6B video foundation model trained progressively with masked reconstruction, cross-modal contrastive learning, and next-token prediction, achieving state-of-the-art results on 60+ video and audio tasks. |
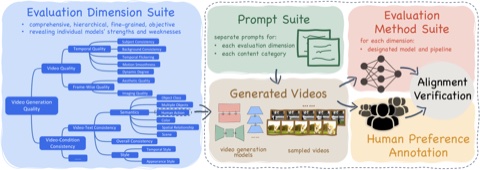 |
VBench: Comprehensive Benchmark Suite for Video Generative Models
Ziqi Huang*, Yinan He*, Jiashuo Yu*, Fan Zhang*, Chenyang Si, Yuming Jiang, Yuanhan Zhang, Tianxing Wu, Qingyang Jin, Nattapol Chanpaisit, Yaohui Wang, Xinyuan Chen, Limin Wang, Dahua Lin, Yu Qiao, Ziwei Liu CVPR, 2024 project page / arXiv / code Decomposes "video generation quality" into 16 hierarchical, disentangled dimensions with tailored prompts and evaluation methods, validated against human preference. |
|
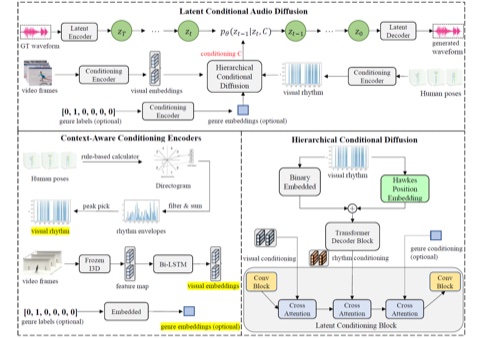
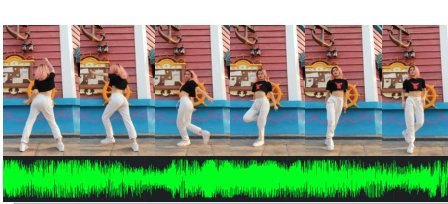
Long-Term Rhythmic Video Soundtracker
Jiashuo Yu, Yaohui Wang, Xinyuan Chen, Xiao Sun, Yu Qiao ICML, 2023 arXiv / code / dataset A latent conditional diffusion model with context-aware conditioning generates long-term, rhythm-synchronized soundtracks for dance and sports videos. |
 |
Learning Music-Dance Representations through Explicit-Implicit Rhythm Synchronization
Jiashuo Yu, Junfu Pu, Ying Cheng, Rui Feng, Ying Shan IEEE Transactions on Multimedia (TMM), 2023 arXiv Self-supervised music-dance representations learned by synchronizing visual rhythms (dance motion) with audio rhythms (music onsets), transferable to dance classification, retrieval, and retargeting. |
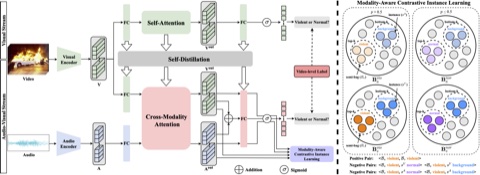 |
Modality-Aware Contrastive Instance Learning with Self-Distillation for Weakly-Supervised Audio-Visual Violence Detection
Jiashuo Yu*, Jinyu Liu*, Ying Cheng, Rui Feng, Yuejie Zhang ACM Multimedia, 2022 arXiv / code Modality-aware contrastive instance learning and self-distillation close the audio-visual modality gap, giving state-of-the-art violence detection on XD-Violence with under 1M parameters. |
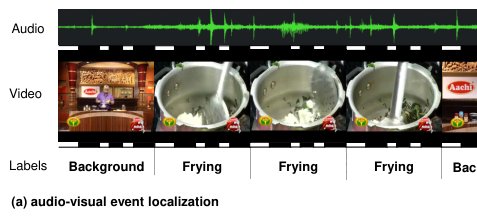 |
MM-Pyramid: Multimodal Pyramid Attentional Network for Audio-Visual Event Localization and Video Parsing
Jiashuo Yu, Ying Cheng, Rui-Wei Zhao, Rui Feng, Yuejie Zhang ACM Multimedia, 2022 arXiv / code Stacked pyramid units with fixed-size attention and dilated convolutions capture audio-visual temporal context at multiple scales for event localization and video parsing. |
 |
MPN: Multimodal Parallel Network for Audio-Visual Event Localization
Jiashuo Yu, Ying Cheng, Rui Feng ICME, 2021 arXiv Parallel classification and localization subnetworks perceive global semantics and unmixed local information for audio-visual event localization. |
Other PublicationsCollaborative work on video foundation models, benchmarks, and datasets. See Google Scholar for the full list.
|
Academic Service
|
|
Website template from Jon Barron. |